
Free Planper month
$0/month
- 1,000 search credits, scrape 1,000 pages, 2 concurrent requests
Loading the latest directory information.
Start here for the decision-making essentials: what Firecrawl does, who it is for, how it is accessed, and the first-party sources behind this profile.
$0/month
$16/month
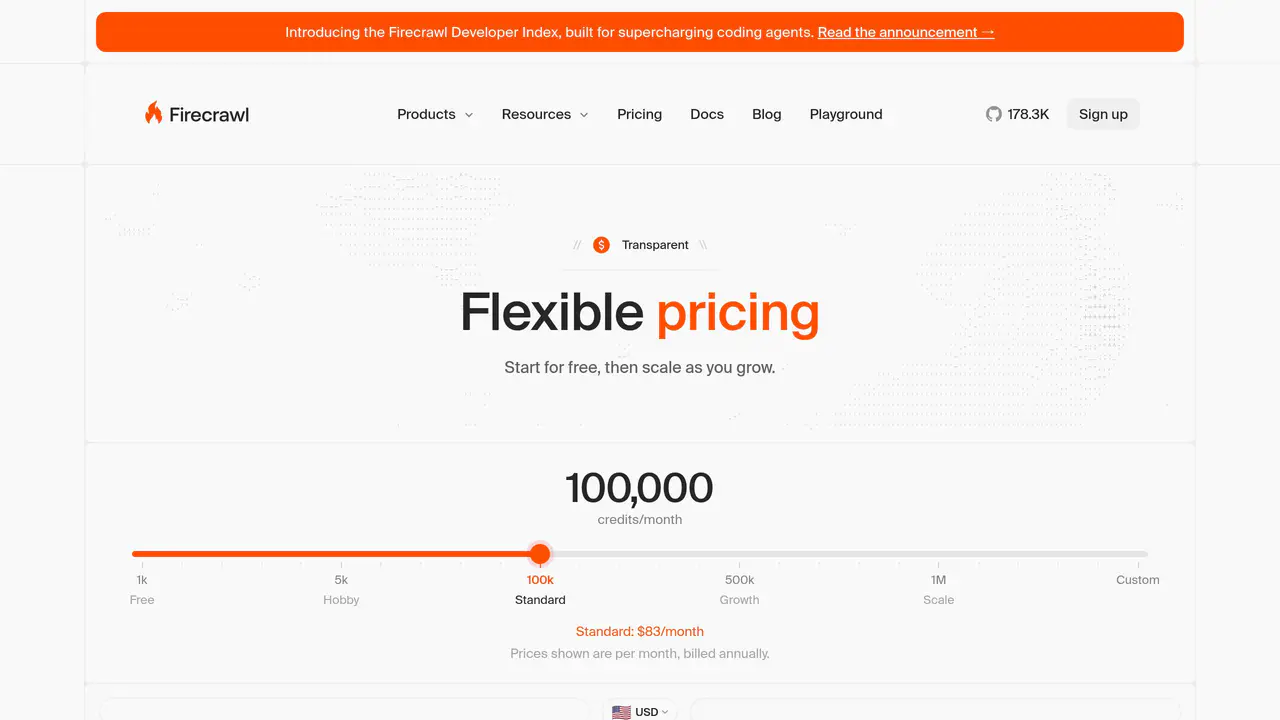
$83/month
$333/month
$599/month
Firecrawl is an open-source API that searches, scrapes, and interacts with the web at scale, converting sources into clean Markdown or structured JSON for AI agents. It offers SDKs in multiple languages and integrations with popular development tools.
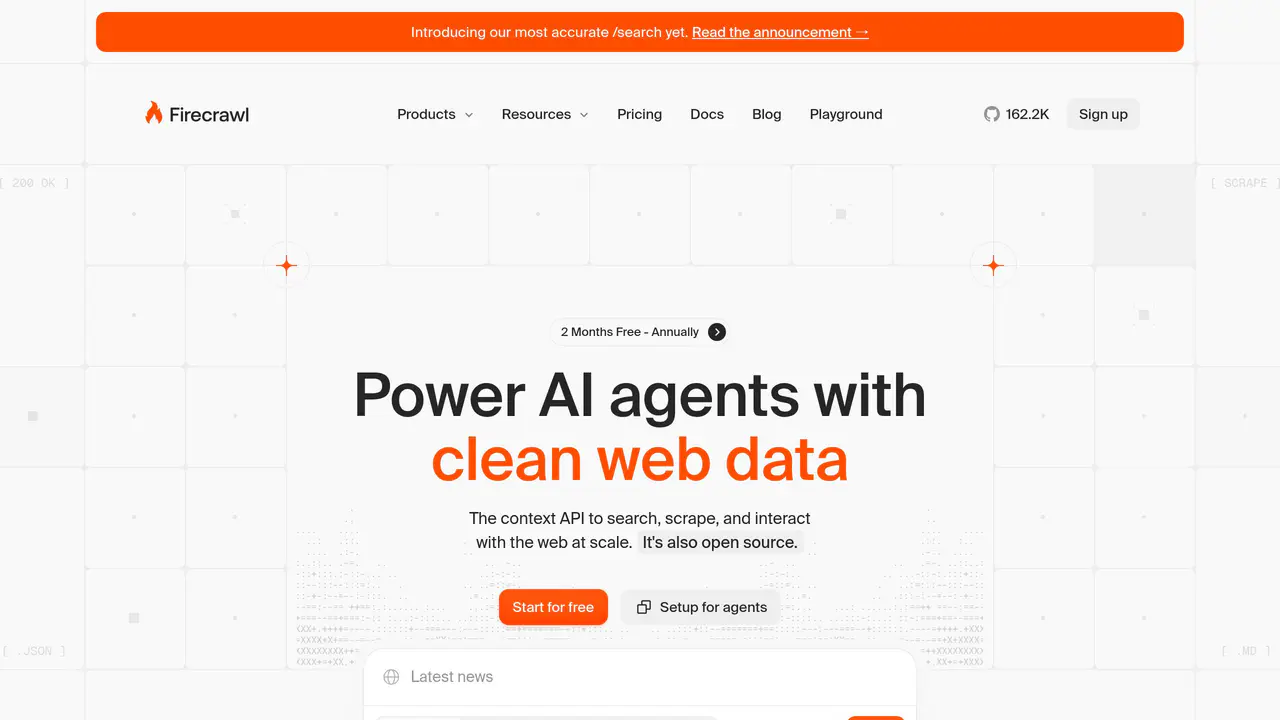
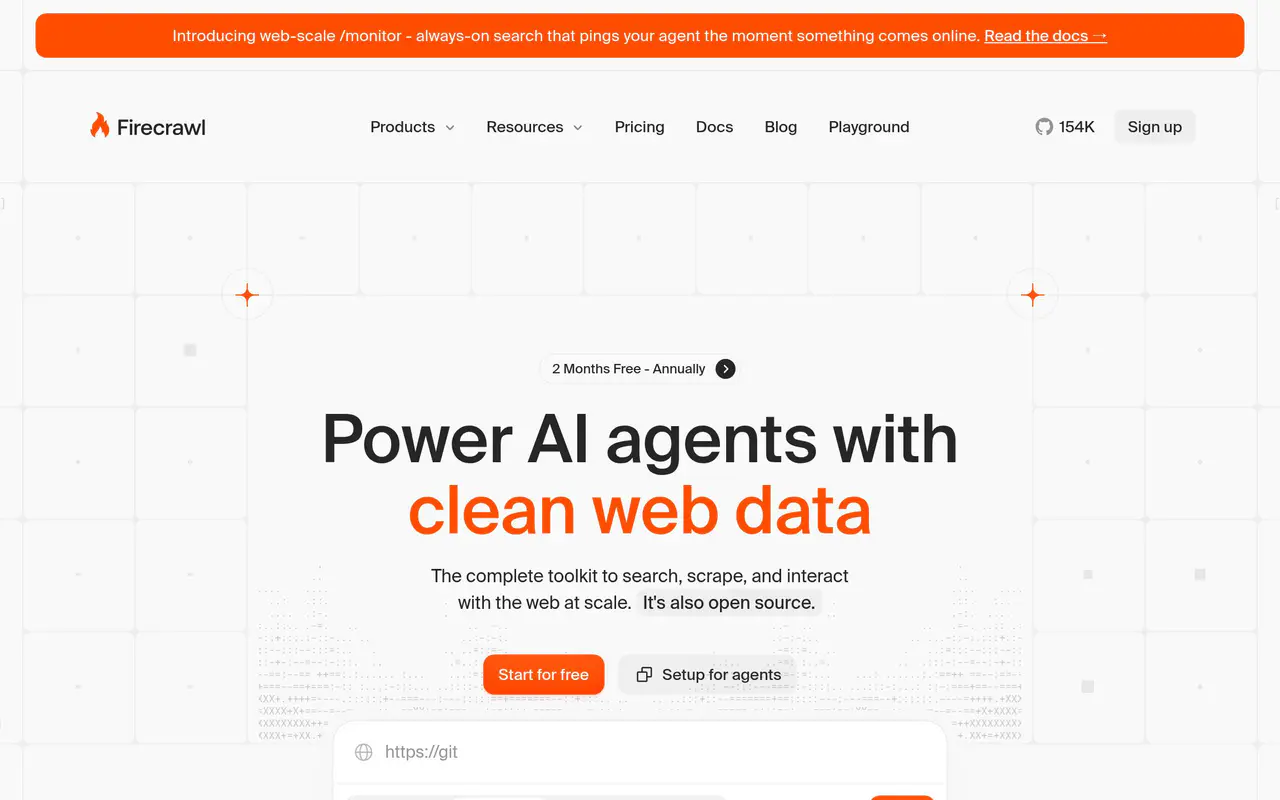
Read-only public captures of Firecrawl’s homepage and verified pricing page. Screenshots are dated, never live embeds, and open full-screen.
Short answers to the questions buyers and builders commonly ask about Firecrawl. Each answer cites the shared ledger below, where every source is listed once.
Search, scrape, and interact with the web at scale via a single context API, returning cle · Search, scrape, and interact with the web at scale via a single API · Converts any URL into clean markdown, structured JSON, screenshots, or semantic text · Firecrawl Developer Index covers 70M+ artifacts across READMEs, external documentation, is
Firecrawl is the context API to search, scrape, and interact with the web at scale. Turn any source into clean Markdown or structured data your agents can ship with.
Over 1.25M developers and 150,000+ companies, including teams at Apple, Canva, and Lovable
Over 1.25M developers and 150,000+ companies build with Firecrawl, including teams at Apple, Canva, and Lovable.
Deep research agents, RAG pipelines, lead enrichment, competitive intelligence, content ge · Powering deep research agents with live web data for market/competitive analysis and techn · Building agentic products that debug their own code by wiring the Developer Index into an · Providing a retrieval layer for training or evaluating coding models and RAG-style pipelin
Teams use Firecrawl for deep research agents, RAG pipelines, lead enrichment, competitive intelligence, content generation, price monitoring, and more.
The Developer Index does not store code and is not a general web search endpoint · Developer Index filters (types, repos, sources, language, topic, license, min_stars, etc.)
the Developer Index does not store code, and it is not a general web search endpoint. It is a purpose-built retrieval layer organized around the artifacts coding agents produce and consume.
Free | $0/month | 1,000 pages, 2 concurrent requests · 10,000 free credits included when connecting Firecrawl through Lovable · Developer search costs 2 credits per 10 results, rounded up
Free Plan A lightweight way to get started. No cost, no card, no hassle. $0 /month Scrape 1,000 pages 2 concurrent requests
Official SDKs for Python, Node.js, Go, Rust, Java, and Elixir, plus a CLI and REST API
Firecrawl has official SDKs for Python, Node.js, Go, Rust, Java, and Elixir, plus a CLI for terminal workflows. You can also call the REST API directly from any language.
This profile connects the jobs Firecrawl is described as handling with its delivery model, access options and the subjects used to match it to related products in this directory.
Each fact points to a recorded source, making it easy to distinguish verified product information from claims that need checking.
HTTP 200 verified twice
Firecrawl - The context API to search, scrape, and interact with the web at scale. 🔥
Search, scrape, and interact with the web at scale via a single API · Converts any URL into clean Markdown, structured JSON, screenshots, or semantic text · Used by over 1.25M developers and 150,000+ companies including Apple, Canva, and Lovable
Search, scrape, and interact with the web at scale via a single context API, returning clean Markdown or structured data for AI agents
Deep research agents, RAG pipelines, lead enrichment, competitive intelligence, content generation, and price monitoring for AI applications needing live web data
Over 1.25M developers and 150,000+ companies, including teams at Apple, Canva, and Lovable
Free | $0/month | 1,000 pages, 2 concurrent requests
Official SDKs for Python, Node.js, Go, Rust, Java, and Elixir, plus a CLI and REST API
Official MCP server and agent skills compatible with Cursor, Claude Code, Windsurf, and Codex
Largest open source repo in the web scraping space with over 150K GitHub stars and 2.5M+ weekly SDK downloads
Vulnerability disclosure program managed through Bugcrowd with safe harbor for good-faith research
Search, scrape, and interact with the web at scale via a single API
A concise view of the jobs, capabilities and integrations described in the recorded product sources.
Documented product formats, platforms and official distribution destinations. Availability can vary by region and plan.
A concise history of software releases and material product changes. Events appear only when a dated source supports what changed.
Showing the newest updates and meaningful milestones. Open an entry for its summary and source.
Firecrawl launched a specialized developer index covering 70M+ artifacts (READMEs, docs, issues, PRs, OpenAPI specs) with semantic retrieval and metadata filters, queryable via API, CLI, MCP, and SDKs.
View source [6]Facts, answers, structured details, milestones and primary resource links cite this shared ledger. Each external page appears once; release tags from the same GitHub project are grouped under one release history.
These tools share a workflow, capability or audience with Firecrawl. They may complement it rather than replace it, and are not presented as integrations or endorsements.
Converts any URL into clean markdown, structured JSON, screenshots, or semantic text
Founded in 2022 as part of Y Combinator
San Francisco
Founded by Caleb Peffer (Co-Founder & CEO), Eric Ciarla (Co-Founder & Chief Growth Officer), and Nicolas Silberstein Camara (Co-Founder & CTO)
Firecrawl is an open source project, described as one of the fastest growing in the world
Integration with Lovable for building web data apps without writing code
Available as an official ChatGPT plugin
Available as an official Replit Connector
Lockdown Mode for /scrape serves results exclusively from Firecrawl's index with zero data retention by default
10,000 free credits included when connecting Firecrawl through Lovable
Firecrawl Developer Index covers 70M+ artifacts across READMEs, external documentation, issues, pull requests, and OpenAPI specs
SideGuide Technologies, Inc. d/b/a Firecrawl
Delaware, United States
San Francisco, CA (Hybrid roles)
Search, scrape, and interact APIs that turn any web source into clean Markdown or structured JSON data for LLMs and agents
Developer Index with 70M+ artifacts covering READMEs, pull requests, issues, OpenAPI specs, skills, and external documentation, with most sources refreshed daily
Powering deep research agents with live web data for market/competitive analysis and technical investigations, with citations and refresh scheduling
Building agentic products that debug their own code by wiring the Developer Index into an agent's tool loop
Providing a retrieval layer for training or evaluating coding models and RAG-style pipelines
Available via API, CLI, MCP server, and SDKs; plugs into Codex, Claude Code, and Grok Build
JavaScript-rendered sites, docs portals, and PDF-heavy libraries supported via /scrape and /crawl
Described as an open-source framework for crawling URLs
Releasing half of the DevDex benchmark dataset plus the evaluation harness as open source
Data encrypted in transit via TLS and at rest if requested; access restricted to personnel under contractual confidentiality
The Developer Index does not store code and is not a general web search endpoint
Developer Index filters (types, repos, sources, language, topic, license, min_stars, etc.) are API-only and intentionally not exposed on the CLI or MCP
Building the interface between LLMs and real-time data on the web; 'building the eyes for AGI'
Developer search costs 2 credits per 10 results, rounded up