Developerper month
$10/month (self-serve payment starting)
- 10x higher rate limits than free tier with higher priority processing
Loading the latest directory information.
Start here for the decision-making essentials: what Cerebras does, who it is for, how it is accessed, and the first-party sources behind this profile.
$10/month (self-serve payment starting)
$50/month
$200/month
Cerebras is the go-to platform for fast and effortless AI training. Learn more at cerebras.ai.
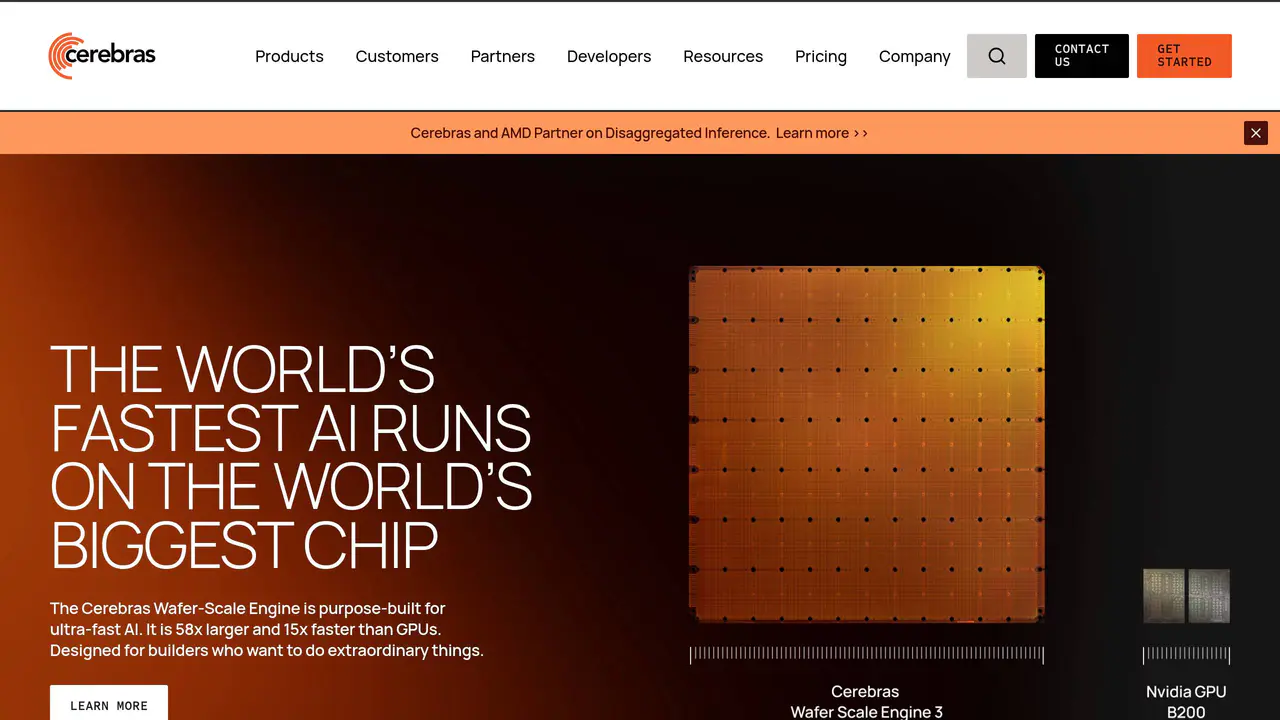
Read-only public captures of Cerebras’s homepage. Screenshots are dated, never live embeds, and open full-screen.
Short answers to the questions buyers and builders commonly ask about Cerebras. Each answer cites the shared ledger below, where every source is listed once.
Up to 30x faster inference than GPUs via the Cerebras CS-4 rack-scale system · Inference, fine-tuning, and pre-training of AI models on customer data · Wafer-Scale Engine keeps an entire model's weights on a single wafer · Cerebras CS-4 delivers up to 30x faster AI inference than GPU systems.
Cerebras CS-4 delivers up to 30x faster inference than GPUs.
AI-powered cybersecurity with real-time detection and response at enterprise scale (CrowdS · Drug discovery acceleration · Voice-first AI companion with low-latency inference · Cerebras Inference powers AlphaSense's Generative Search AI product, running multi-agent r
CrowdStrike and Cerebras deliver AI-powered cybersecurity with ultra-fast inference, enabling real-time AI detection and response at enterprise scale
Developer | starting at $10 | 10x higher rate limits than free tier with higher priority p
Self-serve payment starting at just $10 - 10x higher rate limits than free tier - Higher priority processing
Cerebras-powered inference is available to partners via API
Ninja also provides access to their models via APIs at low costs.
Cerebras Inference is also available through partner APIs · Cerebras is coming to AWS · CS-4 supports disaggregated inference, pairing with AMD Helios or AWS Trainium for prefill · AMD and Cerebras are partnering on a disaggregated inference workflow combining AMD Helios
Get access to Cerebras Inference through our partner APIs
Available on premises and in the cloud · Cerebras solutions are available both on premises and in the cloud via Cerebras Cloud. · Cerebras inference is accessible at cloud.cerebras.ai
Cerebras solutions are available on premises and in the cloud
This profile connects the jobs Cerebras is described as handling with its delivery model, access options and the subjects used to match it to related products in this directory.
Each fact points to a recorded source, making it easy to distinguish verified product information from claims that need checking.
HTTP 200 verified twice
Cerebras
Cerebras Systems Inc. trades on NASDAQ under ticker CBRS · Andrew Feldman is Co-founder & CEO of Cerebras Systems · Headquartered in Sunnyvale, California
Up to 30x faster inference than GPUs via the Cerebras CS-4 rack-scale system
Cerebras Systems Inc.
Andrew Feldman is Co-founder & CEO of Cerebras Systems
Inference, fine-tuning, and pre-training of AI models on customer data
Developer | starting at $10 | 10x higher rate limits than free tier with higher priority processing
Cerebras Inference is also available through partner APIs
Training, inference, and chatbot cloud services
Does not retain inputs and outputs of training, inference, and chatbot services; logs deleted when no longer needed
Enterprise tier includes a dedicated support team with response time guarantees
A concise view of the jobs, capabilities and integrations described in the recorded product sources.
Documented product formats, platforms and official distribution destinations. Availability can vary by region and plan.
A concise history of software releases and material product changes. Events appear only when a dated source supports what changed.
Showing the newest updates and meaningful milestones. Open an entry for its summary and source.
Cerebras and Callosum announce a partnership to deliver ultra-low-latency heterogeneous agentic inference.
View source [1]AMD and Cerebras Systems announced a technical partnership to deliver a disaggregated AI inference solution combining AMD Helios rackscale systems with the Cerebras Wafer-Scale Engine, unveiled at Advancing AI 2026.…
View source [5]AMD and Cerebras announce an industry-leading ultra-low-latency, high-throughput AI inference solution combining AMD Helios with the Cerebras Wafer-Scale Engine.
View source [1]Cerebras and Flex expanded their partnership to scale American manufacturing of Cerebras AI supercomputers.
View source [1]Cerebras announced accelerated European expansion to 200MW of AI compute capacity by end of 2027.
View source [1]Cerebras Systems announced the pricing of its initial public offering.
View source [1]Cerebras Systems announced the launch of its initial public offering.
View source [1]Facts, answers, structured details, milestones and primary resource links cite this shared ledger. Each external page appears once; release tags from the same GitHub project are grouped under one release history.
These tools share a workflow, capability or audience with Cerebras. They may complement it rather than replace it, and are not presented as integrations or endorsements.
Cerebras Systems (NASDAQ: CBRS)
Sunnyvale, California
Wafer-Scale Engine keeps an entire model's weights on a single wafer
Available on premises and in the cloud
Cerebras CS-4 AI accelerator (up to 30x faster inference than GPUs)
Cerebras is coming to AWS
AI-powered cybersecurity with real-time detection and response at enterprise scale (CrowdStrike partnership)
Drug discovery acceleration
Voice-first AI companion with low-latency inference
OpenAI GPT-5.3-Codex-Spark powered by Cerebras
Kimi K2.6 trillion-parameter inference for enterprises
Condor Galaxy supercomputer for sovereign AI, frontier model training, and high-speed inference
Cerebras CS-4 delivers up to 30x faster AI inference than GPU systems.
CS-4 is the fourth-generation Cerebras System, built from three new Wafer Scale Engine 3 Turbo (WSE-3 Turbo) processors.
CS-4 delivers more than 1,000 tokens per second on models exceeding 10 trillion parameters.
CS-4 reduces wafer-to-wafer interconnect latency to as low as 2 microseconds.
CS-4 delivers up to 10x more token throughput per watt than the previous CS-3 system.
CS-4 supports disaggregated inference, pairing with AMD Helios or AWS Trainium for prefill while CS-4 handles decoding.
Cerebras solutions are available both on premises and in the cloud via Cerebras Cloud.
The joint AMD and Cerebras inference solution is expected to be available through Cerebras Cloud in the second half of 2026.
AMD and Cerebras are partnering on a disaggregated inference workflow combining AMD Helios rackscale systems with the Cerebras Wafer-Scale Engine.
Cerebras Systems trades on NASDAQ under the ticker symbol CBRS.
Cerebras Inference powers AlphaSense's Generative Search AI product, running multi-agent research workflows with lower latency for enterprise market intelligence.
Cerebras created the world's first wafer-scale processor, designed across a full 300 mm wafer with more than 100x higher fault tolerance than smaller GPUs.
Fast AI inference on a wafer-scale chip
Wafer-Scale Engine with 44 GB of SRAM per wafer-sized chip
Powers OpenAI's GPT-5.6 Sol Ultrafast in the OpenAI API
Cerebras inference is accessible at cloud.cerebras.ai
Cerebras Systems filed a registration statement for a proposed initial public offering.
View source [1]Cerebras Systems closed an $850 million revolving credit facility.
View source [1]OpenAI announced a multibillion-dollar computing partnership with Cerebras for AI compute.
View source [14]