
Enterpriseper month
$0/month platform fee, per-token billing only
- no platform fees, no markups, no seats
- annual commit discounts every token across 300+ models
Loading the latest directory information.
Start here for the decision-making essentials: what Blackbox AI does, who it is for, how it is accessed, and the first-party sources behind this profile.
$0/month platform fee, per-token billing only
Blackbox AI is a frontier inference platform that routes 300+ open and closed models through one OpenAI-compatible endpoint and runs customer-chosen open-weight models as single-tenant dedicated deployments with zero data retention and end-to-end encryption.
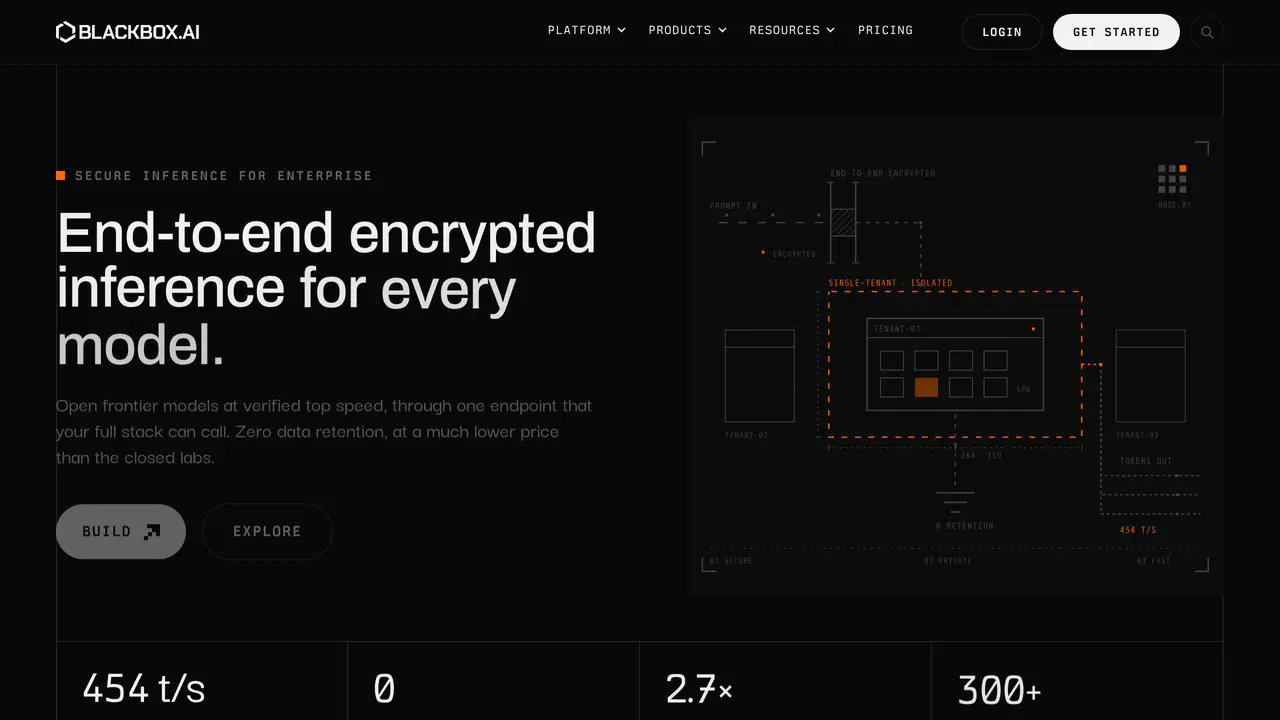
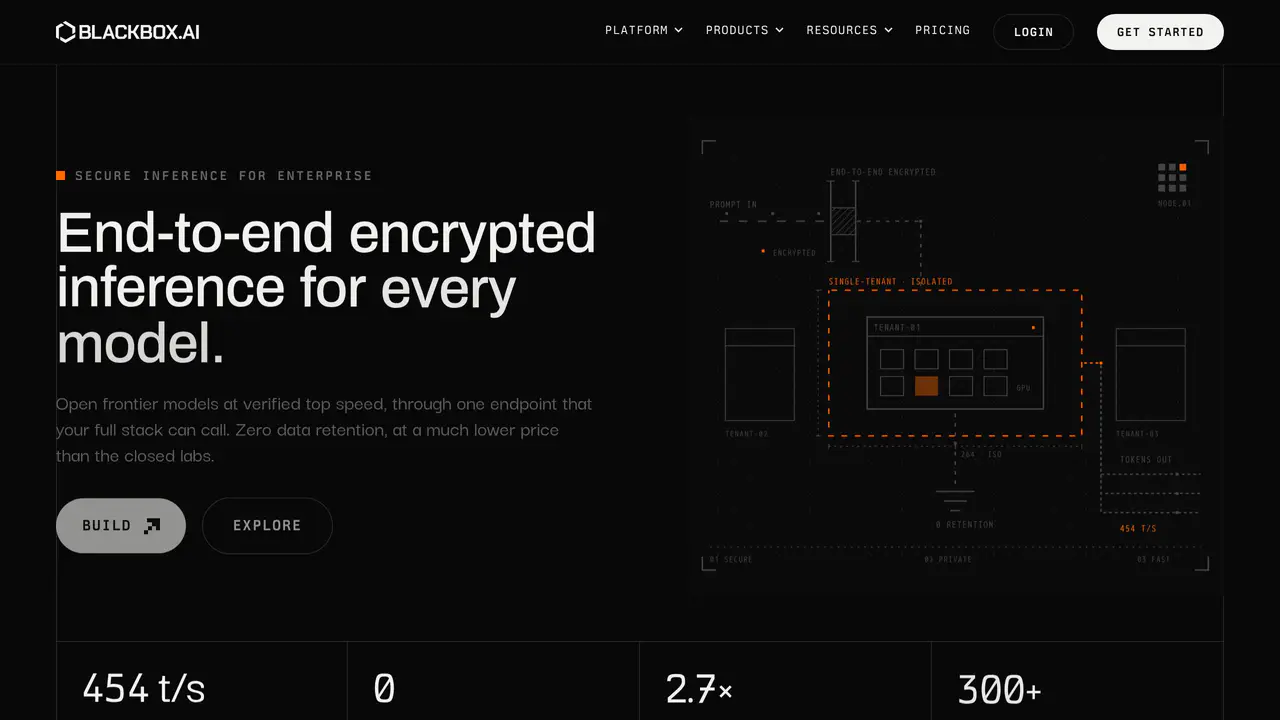
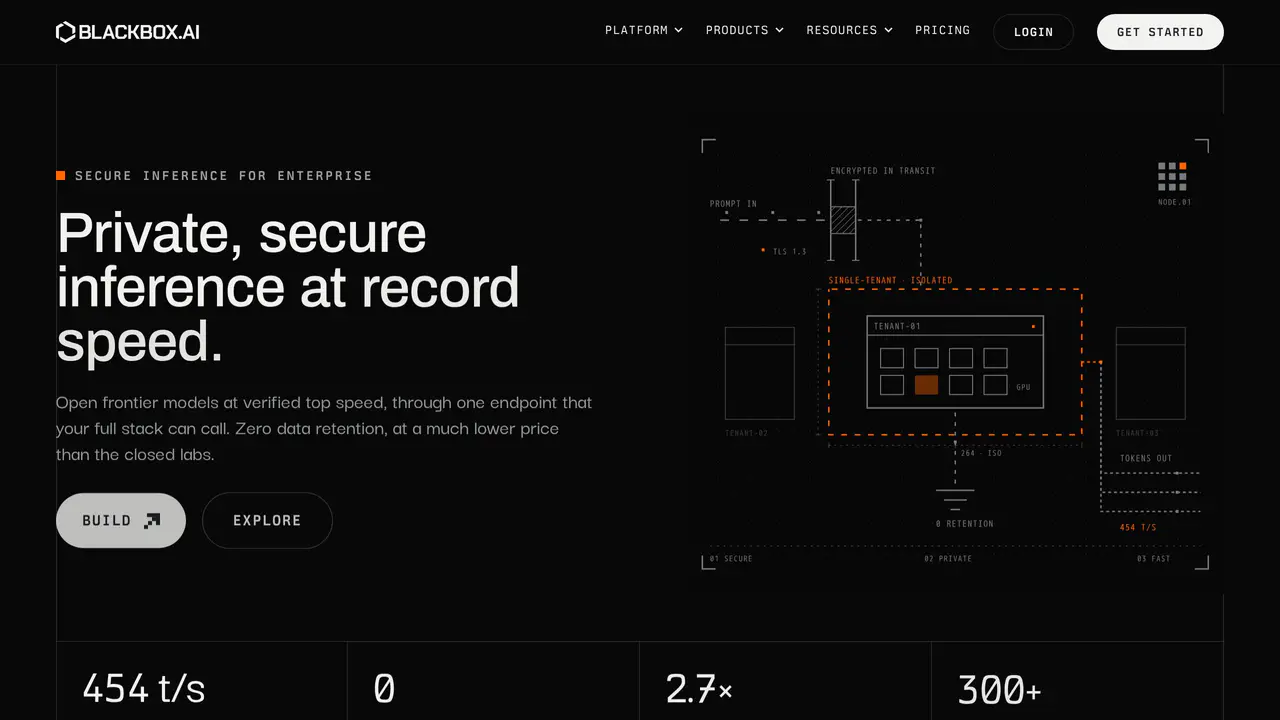
Read-only public captures of Blackbox AI’s homepage. Screenshots are dated, never live embeds, and open full-screen.
Short answers to the questions buyers and builders commonly ask about Blackbox AI. Each answer cites the shared ledger below, where every source is listed once.
Routes 300+ open and closed models through a single endpoint with zero data retention and · Runs a customer-chosen open-weight model on dedicated GPUs isolated to that customer · Routes 300+ open and closed models through one OpenAI-compatible endpoint · Frontier inference platform that runs a user-chosen open-weight model as a dedicated deplo
The Blackbox Router connects you to the 300+ models that we host, with zero data retention and no training.
Enterprise teams deploying AI at scale · Developer / engineering and platform teams (5M+ developers cited)
Blackbox sells to enterprises: it runs the open-weight model that a customer chooses as a dedicated deployment, isolated to that customer.
Enterprise | $0/month platform fee, per-token billing only | no platform fees, no markups,
No platform fees, no markups, and no seats. Priced per token, committed once.
OpenAI-compatible endpoint · Blackbox API (models route through it)
One catalog for 300+ open and closed models: context windows, per-token rates, and capabilities, behind one OpenAI-compatible endpoint.
Single-tenant dedicated deployments for open-weight models via Enterprise Inference · Single-tenant isolated deployment with end-to-end encryption from application to GPU to re
Models marked DEDICATED are open-weight and available through Enterprise Inference as a single-tenant deployment.
End-to-end encryption, Zero Data Retention by default, PII anonymization before model rout · Zero data retention by default; customer-managed keys supported
Prompts, code context, and completions stay in memory for the active request and are discarded after the response. No model training, no prompt review queue, no product analytics copy of the content.
This profile connects the jobs Blackbox AI is described as handling with its delivery model, access options and the subjects used to match it to related products in this directory.
Each fact points to a recorded source, making it easy to distinguish verified product information from claims that need checking.
HTTP 200 verified twice
Blackbox: The high-trust platform for frontier inference
Routes 300+ open and closed models through a single endpoint · Zero data retention and no training on prompts or completions · Enterprise Inference runs a customer-chosen open-weight model on dedicated GPUs isolated t
Routes 300+ open and closed models through a single endpoint with zero data retention and no training
Runs a customer-chosen open-weight model on dedicated GPUs isolated to that customer
Enterprise | $0/month platform fee, per-token billing only | no platform fees, no markups, no seats; annual commit discounts every token across 300+ models
Frontier inference platform combining a multi-model router and dedicated single-tenant model deployment
Blackbox AI Technologies Inc.
535 Mission Street, San Francisco, CA, US
Blackbox AI Technologies Inc.
535 Mission Street, San Francisco, CA, US
AI inference platform / high-trust frontier inference layer
Enterprise teams deploying AI at scale
A concise view of the jobs, capabilities and integrations described in the recorded product sources.
Documented product formats, platforms and official distribution destinations. Availability can vary by region and plan.
A concise history of software releases and material product changes. Events appear only when a dated source supports what changed.
Showing the newest updates and meaningful milestones. Open an entry for its summary and source.
Blackbox made NVIDIA's 30B-parameter open reasoning model, with 3B active parameters, available to Enterprise users; Blackbox reports about one-second startup and 1,200 tokens/sec across 20 straight runs.
View source [3]Blackbox made NVIDIA's Nemotron 3.5 Lightning available for Enterprise: a 30B-parameter open reasoning model (3B active) that starts in about one second and sustains 1,200 tokens/sec across 20 runs.
View source [3]Blackbox AI made NVIDIA's Nemotron 3.5 Lightning, a 30B-parameter open reasoning model (3B active), available for Enterprise customers, claiming ~1-second startup and 1,200 tokens/sec reasoning sustained across 20 runs.
View source [3]Made NVIDIA's 30B-parameter (3B active) open reasoning model Nemotron 3.5 Lightning available on Blackbox Enterprise, sustaining 1,200 tokens/sec with a ~1-second start across 20 runs.
View source [3]A two-model Blackbox reached 90.2% pass@1 on Terminal-Bench v2.1, leading the Artificial Analysis leaderboard by using a sandbox-executing critic to gate exactly one graded answer per task.
View source [1]Facts, answers, structured details, milestones and primary resource links cite this shared ledger. Each external page appears once; release tags from the same GitHub project are grouped under one release history.
These tools share a workflow, capability or audience with Blackbox AI. They may complement it rather than replace it, and are not presented as integrations or endorsements.
Routes 300+ open and closed models through one OpenAI-compatible endpoint
OpenAI-compatible endpoint
Single-tenant dedicated deployments for open-weight models via Enterprise Inference
End-to-end encryption, Zero Data Retention by default, PII anonymization before model routing
ECDH + AES-256-GCM end-to-end encryption with hardware attestation
300+ open and closed models available (225+ with listed pricing)
Open-weight models available as DEDICATED single-tenant deployments
#1 fastest Nemotron 3 Ultra provider at 454.4 tokens/sec, 47% ahead of runner-up
Blackbox AI Technologies Inc. (legal entity Cours Connecte Inc.)
535 Mission Street, San Francisco, CA, US
Site, Desktop Application, Browser Extension, Visual Studio Code Extension, and API
Frontier inference platform that runs a user-chosen open-weight model as a dedicated deployment, or routes 300+ models through one endpoint
Single-tenant isolated deployment with end-to-end encryption from application to GPU to response; air-gapped on request
Zero data retention by default; customer-managed keys supported
Personal data processed on systems in the United States
Developer / engineering and platform teams (5M+ developers cited)
Open weights, data, and recipes released under OpenMDW-1.1
Terminal Bench / Terminal Bench 2.1 scores: GLM 5.2 78.1% (vs 77.9% reference), NVIDIA Ultra 55% (vs 53.9%), Kimi K2.7 71.9% (vs 67%); Nemotron 3.5 Lightning Terminal-Bench 2.0 improved from 58.4 to 69.7
Blackbox AI Technologies Inc.
535 Mission Street, San Francisco, CA, US
US
Terminal-Bench v2.1 - 90.2% pass@1 (AA-basis, 74/82), 89.5% as-run over all graded tasks (77/86)
Two-model stack with a sandbox-executing critic that gates exactly one graded answer per task
Blackbox API (models route through it)
2026-07-21
HTTP 200 verified
BLACKBOX AI
A two-model Blackbox configuration reached 90.2% pass@1 on Terminal-Bench v2.1 (Artificial Analysis methodology, 74/82), leading the leaderboard, by using a sandbox-executing critic to gate exactly one graded answer per task.
View source [1]Reported that serving GLM 5.2, NVIDIA Ultra, and Kimi K2.7 through the Blackbox API improved throughput and latency without retraining or changing weights, with no observed quality regression.
View source [6]Artificial Analysis independently verified Blackbox AI as the fastest Nemotron 3 Ultra provider at 454.4 tokens per second, 47% ahead of the runner-up.
View source [13]Blackbox reported that Artificial Analysis ranked it the fastest Nemotron 3 Ultra provider at 454.4 tokens/sec, 47% ahead of the runner-up at roughly a third of the price.
View source [13]Blackbox reported that its API improved throughput and reduced latency without retraining or changing model weights, with no observed quality regression against GLM 5.2, NVIDIA Ultra, and Kimi K2.7 references.
View source [6]Blackbox stated its API delivers higher throughput and lower latency without retraining or changing model weights, with no observed regression against published GLM 5.2, NVIDIA Ultra, and Kimi K2.7 references.
View source [6]Blackbox reported that serving models through its API gives higher throughput and lower latency with no observed quality regression against the published GLM 5.2, NVIDIA Ultra, and Kimi K2.7 references.
View source [6]