Apache Pinot is an open-source distributed OLAP database, originally developed at LinkedIn and open-sourced on June 10, 2015. It delivers sub-second queries on fresh data at very high concurrency with petabyte-scale performance for user-facing apps and AI agents.
Start here for the decision-making essentials: what Apache Pinot does, who it is for, how it is accessed, and the first-party sources behind this profile.
PricingCurrent signal
See official pricing
Platforms
Web
API accessNot public
FoundedNot disclosed by source
AvailabilityWeb / remote
LicenseOpen-source
Best suited to
Source-backed fit
Real-time analytics for user-facing applications Real-time analytics for AI agents Organizations needing sub-second latency on fresh data Petabyte-scale analytics workloads High-concurrency query environments Streaming data analytics scenarios
Official site snapshots
See the official site at a glance
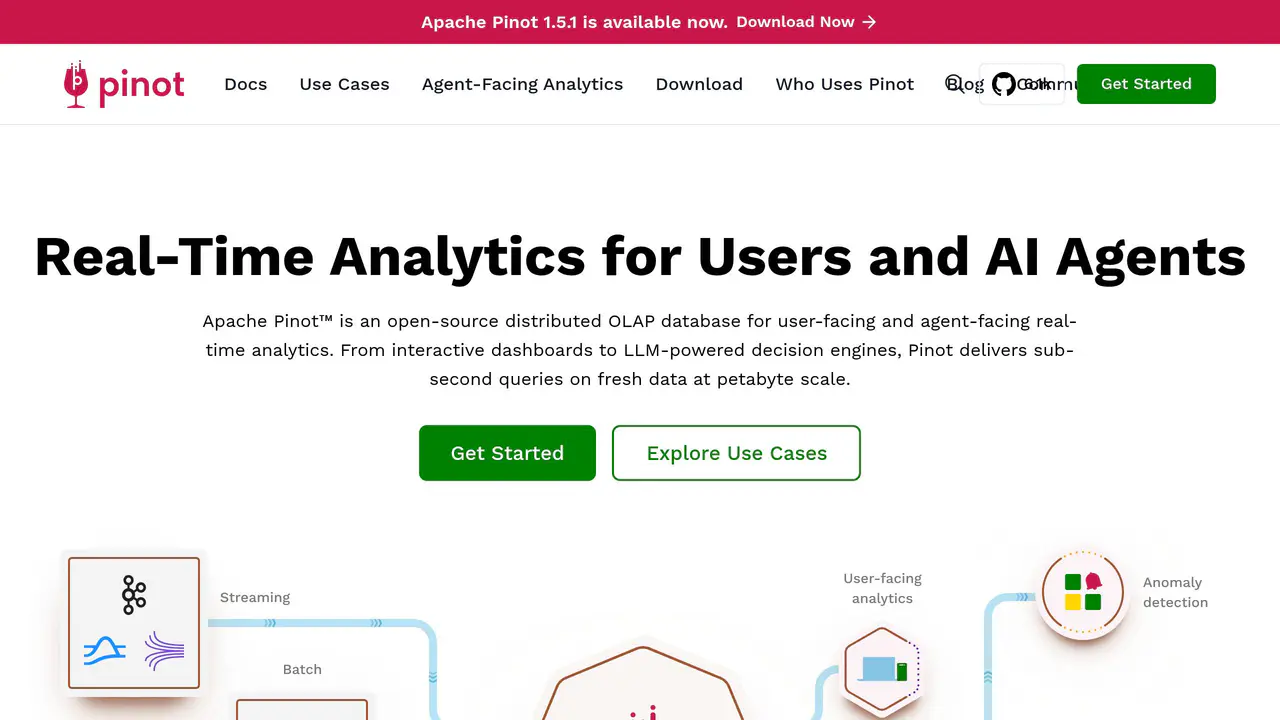
Read-only public captures of Apache Pinot’s homepage. Screenshots are dated, never live embeds, and open full-screen.
Short answers to the questions buyers and builders commonly ask about Apache Pinot. Each answer cites the shared ledger below, where every source is listed once.
01What does Apache Pinot say it can do?
Sub-second queries on fresh data at very high concurrency · Petabyte-scale performance
delivering sub-second queries on fresh data at very high concurrency
This profile connects the jobs Apache Pinot is described as handling with its delivery model, access options and the subjects used to match it to related products in this directory.
Common use cases
Querying fresh streaming data with sub-second latency
Real-time analytics for user-facing apps
Real-time analytics for AI agents
Ingesting streaming data from Apache Kafka
Building real-time analytics solutions on AWS
Real-time analytics for user-facing apps and AI agents
Primary use casesQuerying fresh streaming data with sub-second latency, Real-time analytics for user-facing apps, Real-time analytics for AI agents, Ingesting streaming data from Apache Kafka, Building real-time analytics solutions on AWS, Real-time analytics for user-facing apps and AI agents, Querying fresh streaming data
What to verify before adopting
Evolution and major updates
Apache Pinot timeline
A concise history of software releases and material product changes. Events appear only when a dated source supports what changed.
Research in progress
Scheduled for research
Building a reliable release history.
This profile is being checked for dated releases and material product changes. Nothing appears here until the exact date and event can be verified from a recorded source.
Dated event Short explanation Original source
Citation ledger
Recorded sources
2 unique pages
Facts, answers, structured details, milestones and primary resource links cite this shared ledger. Each external page appears once; release tags from the same GitHub project are grouped under one release history.
1pinot.apache.org 34 facts · 3 answers · 1 snapshot source · Official site
These tools share a workflow, capability or audience with Apache Pinot. They may complement it rather than replace it, and are not presented as integrations or endorsements.
Open-source distributed OLAP database · Originally developed at LinkedIn · Distributed architecture with columnar storage
Application type
Open-source distributed OLAP database
License
Open-source
Capability
Sub-second queries on fresh data
Capability
Very high concurrency
Capability
Real-time analytics on streaming data
Use case
User-facing real-time analytics applications
Use case
AI agent-facing real-time analytics applications
Deployment
Distributed (cluster-based) deployment
Modality
Streaming data (real-time)
Source-supported facts
Open-source distributed OLAP database · Sub-second query latency on fresh data · Petabyte-scale performance
Capability
Open-source distributed OLAP database
Capability
Sub-second query latency on fresh data
Capability
High concurrency
Capability
Columnar storage with distributed architecture
Use case
User-facing and agent-facing real-time analytics
Use case
Querying fresh streaming data with sub-second latency
Open source
Open-source
Model version
1.4
Release date
September 30th, 2025
Integration
Apache Kafka
Source-supported facts
Application type: OLAP database · Open-source · Originally developed at LinkedIn
Application type
OLAP database
Use case
User-facing applications and AI agents
Capability
Real-time analytics on fresh streaming data with sub-second latency
Data & analytics · ToolClickHouseClickHouse is a fast open-source column-oriented database management system that allows generating analytical data reports in real-time using SQL queriesAlso mapped to Data & analytics
Data & analytics · ToolCockroachDBCockroachDB is a cloud-agnostic, PostgreSQL-compatible distributed SQL database by Cockroach Labs offering zero-data-loss resilience, multi-cloud deployment, native vector search, and horizontal scaling from small workloads to hundreds of nodes and petabytes.Also mapped to Data & analytics
Data & analytics · ToolCubeCube is an agentic analytics platform built on a universal semantic layer, delivering AI-native business intelligence and embedded analytics with governed, trustworthy answers for internal and customer-facing use.Also mapped to Data & analytics
Data & analytics · ToolDecodableDecodable is a fully-managed, serverless, cloud-native stream processing platform built on Apache Flink and Debezium. It enables pipelines in SQL, Java, or Python with built-in connectors and CDC, offering SOC 2 Type II, HIPAA, and GDPR compliance.Also mapped to Data & analytics