


HTTP 200 verified twice
Finding your next stop…
Loading the latest directory information.
Loading the latest directory information.
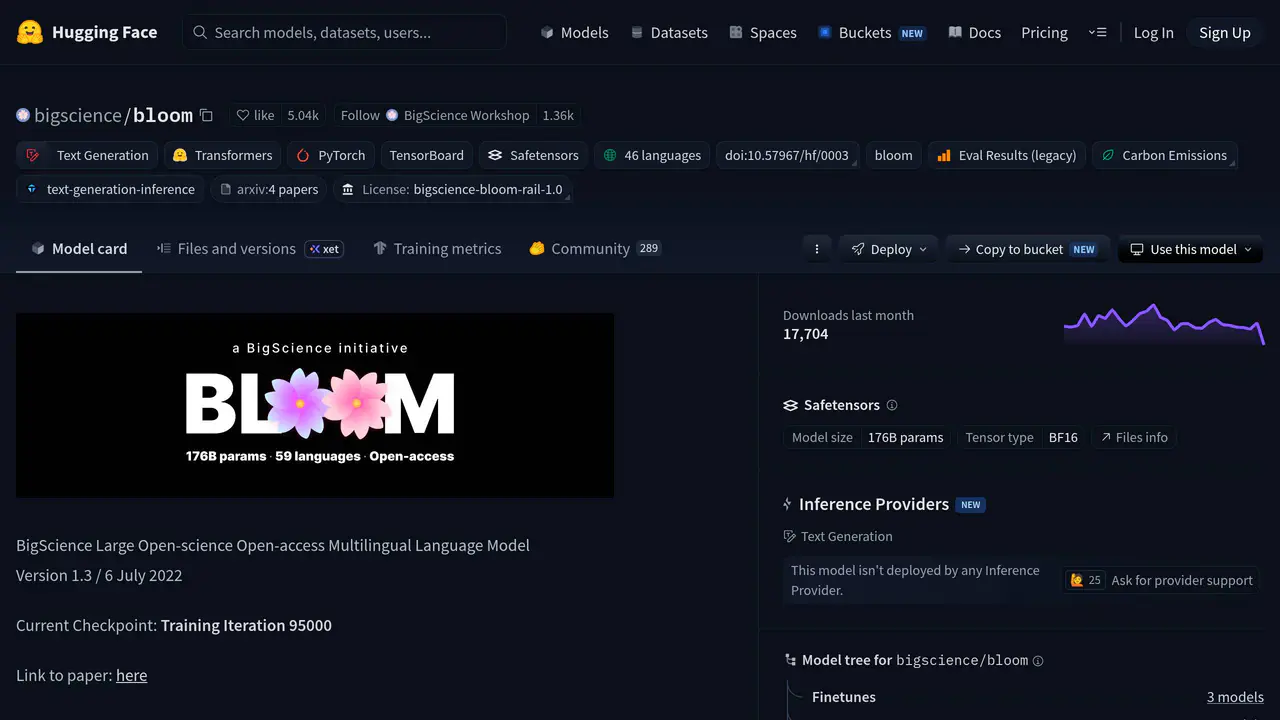
BLOOM is a 176B-parameter open-access multilingual autoregressive Large Language Model released July 2022 under the RAIL License v1.0, supporting 46 natural languages and 13 programming languages with a 2048-token context window.
Start here for the decision-making essentials: what Bloom does, who it is for, how it is accessed, and the first-party sources behind this profile.
See official pricing
Read-only public captures of Bloom’s homepage and verified pricing page. Screenshots are dated, never live embeds, and open full-screen.
Published specifications and use cases for Bloom. Repository dates are kept separate from the model's original release date.
Short answers to the questions buyers and builders commonly ask about Bloom. Each answer cites the shared ledger below, where every source is listed once.
Autoregressive text generation; can be instructed to perform text tasks it hasn't been exp
BLOOM can also be instructed to perform text tasks it hasn't been explicitly trained for, by casting them as text generation tasks.
Text generation, Information Extraction, Question Answering, Summarization
Text generation - Exploring characteristics of language generated by a language model - Examples: Cloze tests, counterfactuals, generations with reframings - Tasks that leverage language models include: Information Extraction, Question Answering, Summarization
Using the model in high-stakes settings is out of scope; not designed for critical decisio
Using the model in high-stakes settings is out of scope for this model. The model is not designed for critical decisions nor uses with any material consequences on an individual's livelihood or wellbeing. The model outputs content that appears factual but may not be correct.
Monday, 11 July 2022 (Release Date Estimate)
Release Date Estimate: Monday, 11.July.2022
2048 tokens
Sequence length of 2048 tokens used (see BLOOM tokenizer, tokenizer description)
176,247,271,424 parameters (3,596,615,680 embedding parameters)
176,247,271,424 parameters: - 3,596,615,680 embedding parameters
This profile connects the jobs Bloom is described as handling with its delivery model, access options and the subjects used to match it to related products in this directory.
Each fact points to a recorded source, making it easy to distinguish verified product information from claims that need checking.
HTTP 200 verified twice
bigscience/bloom · Hugging Face
Model family: BLOOM (BigScience Large Open-science Open-access Multilingual Language Model · Model version: 1.3 / 6 July 2022 · Release Date Estimate: Monday, 11 July 2022
BLOOM
1.3 / 6 July 2022
Monday, 11 July 2022 (Release Date Estimate)
176,247,271,424 parameters (3,596,615,680 embedding parameters)
Decoder-only Transformer with ALiBI positional encodings and GeLU activation functions; 70 layers, 112 attention heads, 14336-dimensional hidden layers
2048 tokens
Text (autoregressive Large Language Model)
46 natural languages and 13 programming languages
RAIL License v1.0
A concise view of the jobs, capabilities and integrations described in the recorded product sources.
Documented product formats, platforms and official distribution destinations. Availability can vary by region and plan.
A concise history of software releases and material product changes. Events appear only when a dated source supports what changed.
Showing the newest updates and meaningful milestones. Open an entry for its summary and source.
The public model repository was created on Hugging Face. This repository date may differ from the model's original release date.
View source [1]Facts, answers, structured details, milestones and primary resource links cite this shared ledger. Each external page appears once; release tags from the same GitHub project are grouped under one release history.
These tools share a workflow, capability or audience with Bloom. They may complement it rather than replace it, and are not presented as integrations or endorsements.
Autoregressive text generation; can be instructed to perform text tasks it hasn't been explicitly trained for by casting them as text generation tasks
Text generation, Information Extraction, Question Answering, Summarization
Using the model in high-stakes settings is out of scope; not designed for critical decisions nor uses with material consequences on an individual's livelihood or wellbeing; outputs may appear factual but may not be correct
Model family: BigScience Large Open-science Open-access Multilingual Language Model (BLOOM · 176,247,271,424 parameters · Autoregressive Large Language Model trained to continue text from a prompt
BigScience Large Open-science Open-access Multilingual Language Model (BLOOM)
Autoregressive Large Language Model trained to continue text from a prompt on vast amounts of text data
176,247,271,424 parameters
Decoder-only Transformer with Layer-normalized word embeddings (StableEmbedding), ALiBI positional encodings, and GeLU activation functions
2048 tokens sequence length
11 July 2022
Text generation, Information Extraction, Question Answering, and Summarization
1.6TB of pre-processed text converted into 350B unique tokens across 46 natural languages and 13 programming languages
Trained on Jean Zay Public Supercomputer using 384 A100 80GB GPUs (48 nodes) with NVLink and Omni-Path interconnect, located in Île-de-France, France
HumanEval python pass@1: 0.155; pass@10: 0.328; pass@100: 0.572 (reported)
Hugging Face Space at https://huggingface.co/spaces/bigscience/petals-api
Distributed inference API for the Bloom language model (Space status: paused)
The bigscience/petals-api Space has been paused and is not currently available
AIApplication
Advance and democratize artificial intelligence through open source and open science
Native SDKs provided for Python (huggingface_hub InferenceClient) and JavaScript (@huggingface/inference), plus OpenAI-compatible REST endpoint
OpenAI-compatible chat completions endpoint at https://router.huggingface.co/v1/chat/completions
Serverless inference through Hugging Face Inference Providers proxy (e.g., Cerebras, Groq, Together, Replicate, Fal AI)
Chat completion (LLM and VLM), feature extraction, text-to-image, text-to-video, and speech-to-text across integrated inference providers
Free tier included, with additional credits for PRO users and Team & Enterprise organizations
176,247,271,424 parameters (176B) · Version 1.3 / 6 July 2022 · Decoder-only Transformer modified from Megatron-LM GPT2
BLOOM (BigScience Large Open-science Open-access Multilingual Language Model)
Version 1.3 / 6 July 2022
176,247,271,424 parameters (176B)


