Start here for the decision-making essentials: what Chroma does, who it is for, how it is accessed, and the first-party sources behind this profile.
PricingCurrent signal
$0.0075 per TiB queried and $0.09 per GiB returned for reads
Platforms
Web
API accessNot public
FoundedNot disclosed by source
AvailabilityWeb / remote
LicenseApache 2.0
Best suited to
Source-backed fit
Teams building RAG and agentic AI applications Developers needing multimodal embedding search Organizations requiring flexible self-hosted or managed deployment AI/ML engineers using multiple embedding providers
Official site snapshots
See the official site at a glance
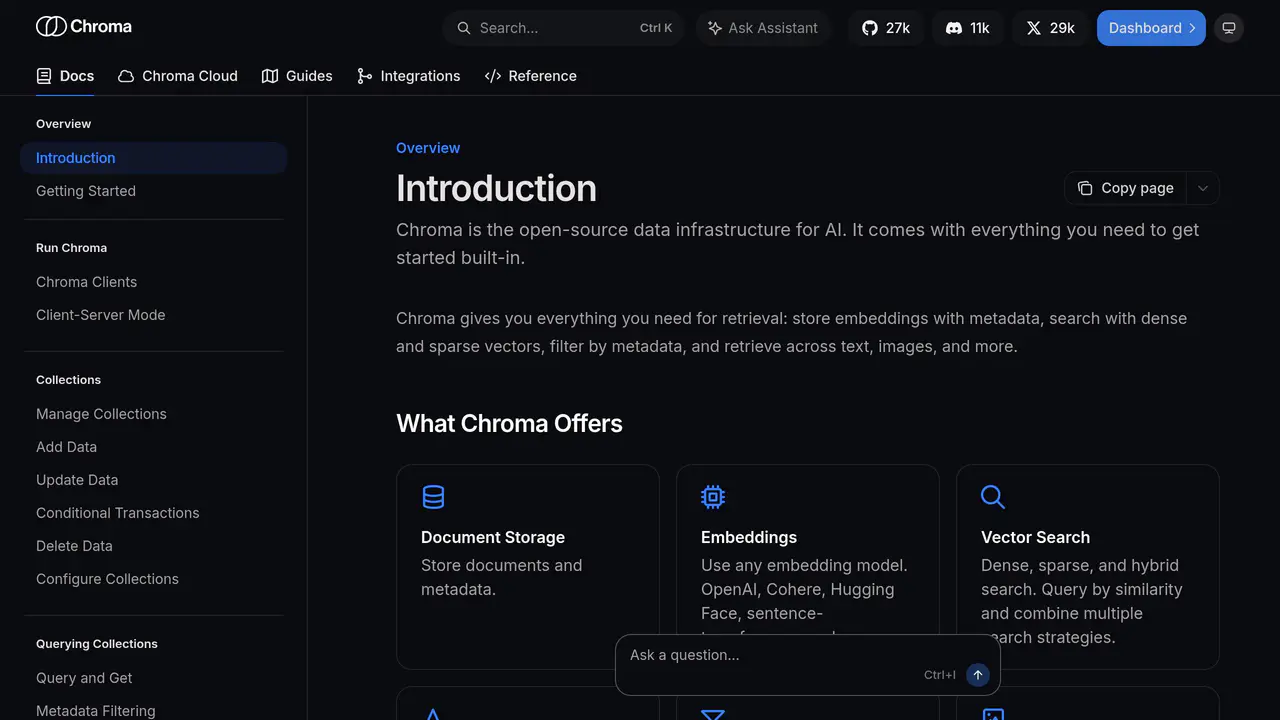
Read-only public captures of Chroma’s homepage. Screenshots are dated, never live embeds, and open full-screen.
AI infrastructure · Tool
Chroma
Decision-ready
Chroma is an open-source (Apache 2.0) data infrastructure for AI that stores embeddings and supports dense, sparse, hybrid, keyword, and regex search across text, images, and audio. It runs as self-hosted single-node, distributed, or managed Chroma Cloud, with AWS CloudFormation deployment, a CLI, and Mem0 integration.
Short answers to the questions buyers and builders commonly ask about Chroma. Each answer cites the shared ledger below, where every source is listed once.
01What does Chroma say it can do?
Stores embeddings with metadata, searches with dense and sparse vectors, filters by metada · Supports dense, sparse, and hybrid search as well as keyword and regex search without embe · Instant copy-on-write collection forking is offered in Chroma Cloud, letting forks share d · CLI provides DB management, collection copying and browsing operations
store embeddings with metadata, search with dense and sparse vectors, filter by metadata, and retrieve across text, images, and more
Build agents that iteratively search and refine results for complex queries · Index codebases to power coding agents using AST-aware chunking · Forking supports data versioning/checkpointing and git-like workflows (e.g., indexing a br · Sample AI applications powered by Chroma for learning retrieval and building AI apps
Build agents that iteratively search and refine results for complex queries.
03What should teams verify before adopting Chroma?
Collection forking is not supported on single-node Chroma storage engine; available in Chr · Vacuuming blocks all reads and writes to the database while running · CLI collection browser initially loads only 100 records, with more loaded on scroll · Local Chroma may temporarily lack some features or behaviors available in the distributed
Forking is available in Chroma Cloud only. The storage engine on single-node Chroma does not support forking.
04What pricing information is available for Chroma?
$0.0075 per TiB queried and $0.09 per GiB returned for reads · $0.33 per GiB per month for storage (prorated by the hour) · Fork call | $0.03 per fork call | incremental blocks written after the fork (copy-on-write
Chroma provides a fork API accessible from Python or JavaScript SDKs · API key authentication available for headless environments via Chroma Cloud dashboard · Chroma Cloud can be configured via the environment variables CHROMA_API_KEY, CHROMA_TENANT
Works with any embedding model including OpenAI, Cohere, Hugging Face, and sentence-transf · Chroma integrates with Mem0 as a vector store provider, configured via vector_store.provid · CLI profile authentication uses an API key and tenant ID for Chroma Cloud, stored in .chro
Use any embedding model. OpenAI, Cohere, Hugging Face, sentence-transformers, and more.
This profile connects the jobs Chroma is described as handling with its delivery model, access options and the subjects used to match it to related products in this directory.
Common use cases
Building agents that iteratively refine search results
Indexing codebases for coding agents with AST-aware chunking
Multimodal search across text, images, and audio
Data versioning and git-like workflows via collection forking
$0.0075 per TiB queried and $0.09 per GiB returned for reads · $0.33 per GiB per month for storage (prorated by the hour) · Fork call | $0.03 per fork call | incremental blocks written after the fork (copy-on-write
API
Not publicly listed
Source links
17 recorded
Source-backed
Verified facts
Updated August 30, 2026
Each fact points to a recorded source, making it easy to distinguish verified product information from claims that need checking.
Official website
HTTP 200 verified twice
First-party description
Introduction - Chroma Docs
Source-supported facts
Open-source AI data infrastructure licensed under Apache 2.0 · Stores embeddings with metadata, supports dense, sparse, and hybrid search · Supports keyword and regex search without embeddings
Capability
Stores embeddings with metadata, searches with dense and sparse vectors, filters by metadata, and retrieves across text, images, and more
Capability
Supports dense, sparse, and hybrid search as well as keyword and regex search without embeddings
Integration
Works with any embedding model including OpenAI, Cohere, Hugging Face, and sentence-transformers
Deployment
Can be deployed as a self-hosted database or a managed zero-ops Chroma Cloud database
Use case
Build agents that iteratively search and refine results for complex queries
View 32 more verified facts
Use case
Index codebases to power coding agents using AST-aware chunking
Modality
Indexes and searches images, audio, and other modalities alongside text
Open source
Yes - Chroma is open-source data infrastructure for AI
Pricing
$0.0075 per TiB queried and $0.09 per GiB returned for reads
Practical capabilities
What it helps with
8 documented areas
A concise view of the jobs, capabilities and integrations described in the recorded product sources.
Use case
Building agents that iteratively refine search results
Use case
Indexing codebases for coding agents with AST-aware chunking
Use case
Multimodal search across text, images, and audio
Use case
Data versioning and git-like workflows via collection forking
Use case
Keyword and regex search without embeddings
Use case
Integrating with Mem0 as a vector store provider
Use case
Build agents that iteratively search and refine results for complex queries
Use case
Index codebases to power coding agents using AST-aware chunking
Availability
Where it runs and where to get it
Source checked
Documented product formats, platforms and official distribution destinations. Availability can vary by region and plan.
Cost / license
$0.0075 per TiB queried and $0.09 per GiB returned for reads · $0.33 per GiB per month for storage (prorated by the hour) · Fork call | $0.03 per fork call | incremental blocks written after the fork (copy-on-writeApache 2.0Chroma is the open-source data infrastructure for AITrue — source hosted on GitHub with public issues and pull requestsChroma is open-source data infrastructure for AIYes — Chroma is the open-source data infrastructure for AIYes - Chroma is open-source data infrastructure for AITrue - open-source project accepting contributions via GitHub pull requestsApache 2.0 · Yes - Chroma is open-source data infrastructure for AI · True - open-source project accepting contributions via GitHub pull requests
Application types
Command-line interface tool for managing Chroma Cloud and local Chroma servers
Platforms
Local Chroma server defaults to host `localhost` and port `8000`, configurable via CLI argAvailable via Python and JavaScript packages (chromadb)Chroma provides client libraries for Python, TypeScript, and Rust.
DeploymentCan be deployed as a self-hosted database or a managed zero-ops Chroma Cloud database · Chroma can be run as a local server using the `chroma run` CLI command, with data persiste · Forked collections belong to the same database as the source collection in Chroma Cloud · Hosted Chroma Cloud database service available
LicenseApache 2.0 · Yes - Chroma is open-source data infrastructure for AI · True - open-source project accepting contributions via GitHub pull requests
Model supportNot disclosed by source
Data controlChroma no longer collects product telemetry as of version 1.5.4; users can self-collect ob
Learning curveIntermediate
Primary use casesBuilding agents that iteratively refine search results, Indexing codebases for coding agents with AST-aware chunking, Multimodal search across text, images, and audio, Data versioning and git-like workflows via collection forking, Keyword and regex search without embeddings, Integrating with Mem0 as a vector store provider, Build agents that iteratively search and refine results for complex queries, Index codebases to power coding agents using AST-aware chunking, Forking supports data versioning/checkpointing and git-like workflows (e.g., indexing a br, Sample AI applications powered by Chroma for learning retrieval and building AI apps, The ephemeral in-memory client is recommended for experimenting with different embedding f
What to verify before adopting
Collection forking is not supported on single-node Chroma storage engine; available in Chr
Vacuuming blocks all reads and writes to the database while running
CLI collection browser initially loads only 100 records, with more loaded on scroll
Local Chroma may temporarily lack some features or behaviors available in the distributed
The PersistentClient reset() method empties and completely resets the database; this opera
Evolution and major updates
Chroma timeline
A concise history of software releases and material product changes. Events appear only when a dated source supports what changed.
Research in progress
Scheduled for research
Building a reliable release history.
This profile is being checked for dated releases and material product changes. Nothing appears here until the exact date and event can be verified from a recorded source.
Dated event Short explanation Original source
Citation ledger
Recorded sources
17 unique pages
Facts, answers, structured details, milestones and primary resource links cite this shared ledger. Each external page appears once; release tags from the same GitHub project are grouped under one release history.
These tools share a workflow, capability or audience with Chroma. They may complement it rather than replace it, and are not presented as integrations or endorsements.
$0.33 per GiB per month for storage (prorated by the hour)
Integration
Chroma integrates with Mem0 as a vector store provider, configured via vector_store.provider = "chroma" with collection_name and path settings
Capability
Instant copy-on-write collection forking is offered in Chroma Cloud, letting forks share data blocks with the source collection
Limitation
Collection forking is not supported on single-node Chroma storage engine; available in Chroma Cloud only
Pricing
Fork call | $0.03 per fork call | incremental blocks written after the fork (copy-on-write); unchanged data remains shared
Use case
Forking supports data versioning/checkpointing and git-like workflows (e.g., indexing a branch from a divergence point and applying a diff)
Api
Chroma provides a fork API accessible from Python or JavaScript SDKs
Deployment
Chroma can be run as a local server using the `chroma run` CLI command, with data persisted to a configurable directory
Platform
Local Chroma server defaults to host `localhost` and port `8000`, configurable via CLI arguments or a config_path configuration file
Deployment
Forked collections belong to the same database as the source collection in Chroma Cloud
Capability
CLI provides DB management, collection copying and browsing operations
Capability
Inspect Chroma collections with an in-terminal UI
Capability
Browse collections on Chroma Cloud or a local Chroma server via CLI
Capability
Stores collections of records with IDs, documents, and metadata
Capability
Supports .get() queries on collections via CLI query editor
Capability
Vacuum operation shrinks and optimizes the Chroma database
Deployment
Hosted Chroma Cloud database service available
Deployment
Local Chroma server runs by default at http://localhost:8000
Platform
Available via Python and JavaScript packages (chromadb)
Api
API key authentication available for headless environments via Chroma Cloud dashboard
Limitation
Vacuuming blocks all reads and writes to the database while running
Limitation
CLI collection browser initially loads only 100 records, with more loaded on scroll
Capability
Open-source data infrastructure for AI
License
Apache 2.0
Deployment
Two deployment modes: distributed Chroma and single-node local Chroma
Deployment
Chroma Cloud runs the same open-source distributed system as the self-hosted database
Open source
True - open-source project accepting contributions via GitHub pull requests
Limitation
Local Chroma may temporarily lack some features or behaviors available in the distributed system; restoring 100% feature and API parity is an active goal
AI infrastructure · ToolArthur AIArthur AI provides a unified control plane for trustworthy enterprise AI, delivering agent discovery, observability, guardrails, and governance across the full lifecycle. It supports LLM, tabular, CV, and NLP models with bias detection, cost optimization, and SOC 2 Type II compliance.Also mapped to AI infrastructure
AI infrastructure · ToolBraintrustBraintrust is an enterprise-grade AI observability and evaluation platform for tracing production LLM applications, running experiments on datasets, comparing prompts and models, and catching regressions via online scoring and quality gates.Also mapped to AI infrastructure
AI infrastructure · ToolCerebriumCerebrium is a serverless AI infrastructure platform for real-time, high-performance applications. It provides global, region-aware GPU deployment, sub-second cold starts, instant autoscaling, and hardened gVisor workload isolation, with support for voice agents, video models, LLMs, multimodal pipelines, and large-scale batch jobs.Also mapped to AI infrastructure
AI infrastructure · ToolChromaChroma is open-source Apache 2.0 search infrastructure for AI, offering serverless, scalable vector, full-text, regex, and metadata search on object storage. Available as Chroma Cloud with SOC 2 Type II, CMEK, BYOC, and multi-cloud replication.Also mapped to AI infrastructure